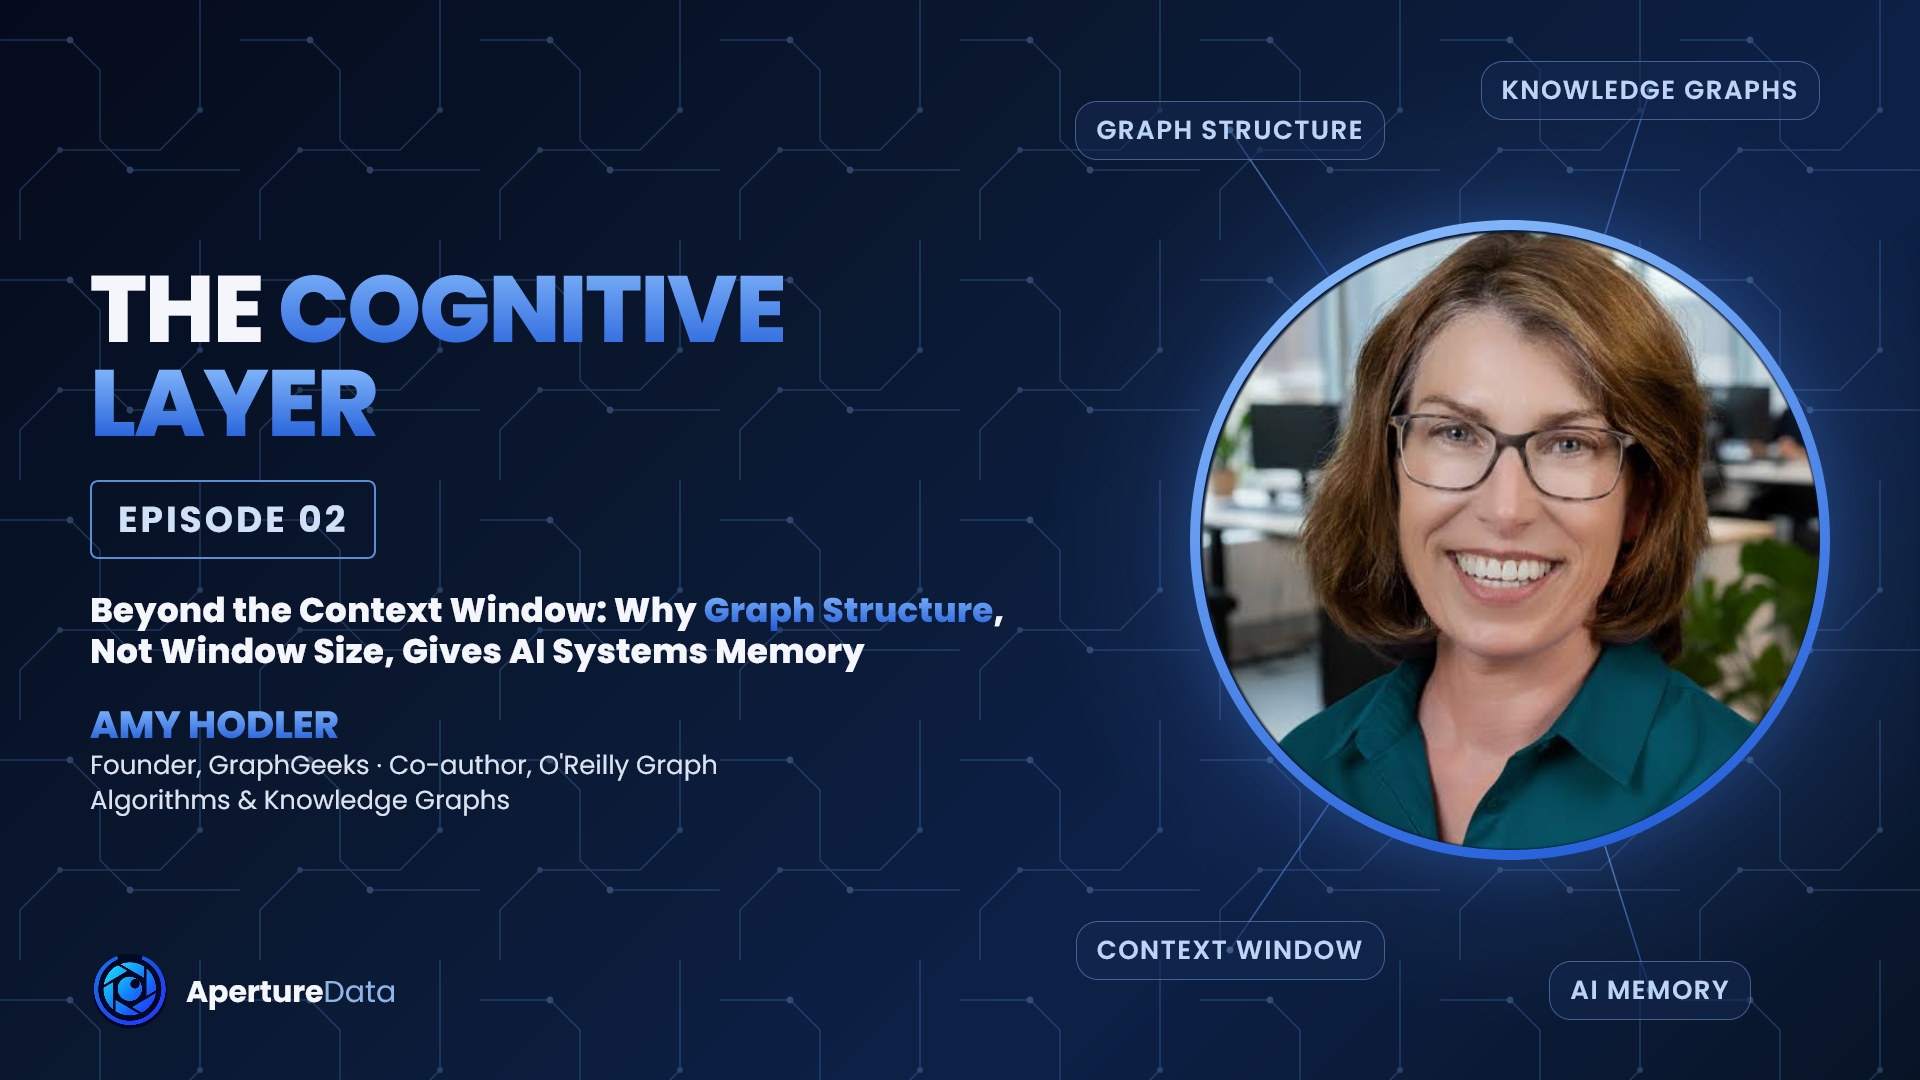


Notes from Episode 2 of The Cognitive Layer, with Amy Hodler
Listen or watch the full conversation: Spotify · YouTube
A common assumption is that a big enough context window means you don't need a separate memory layer. My guest for this episode has spent her career arguing that assumption is wrong: the answer was never just size. It needed structure.
Amy Hodler is the founder of GraphGeeks and co-author of two O'Reilly books, Graph Algorithms and Knowledge Graphs, alongside contributions to Routledge's Massive Graph Analytics and Bloomsbury's AI on Trial. Her path into this work started somewhere unexpected: a book. "A big shift was reading a book called The Information by James Gleick, where he looks at information theory," she told me. "It becomes very clear as you work through the history of how we even look at information, how connected everything is, how one thing leads to another." That book, she said, changed how she saw the world, and set the direction her whole career would take.
Why a Bigger Context Window Doesn't Replace AI Memory
I asked Amy directly: if a company has a million-token context window but no graph backbone to organize it, where does the intelligence actually break down?
Her answer named three separate failure points. The first is what she calls the "lost in the middle" phenomenon:
"LLMs in particular are notorious for ignoring information kind of buried in the middle of a really large context window."
A graph backbone surfaces the relevant, interconnected pieces instead, which prevents token bloat and attention dilution. The second is determinism: a graph enforces structure on top of an otherwise probabilistic response. The third is change over time: a graph can represent how relationships evolve, something a flat context window has no native way to express.
The distinction matters because a list of isolated facts and a graph of connected ones are not the same kind of memory. Amy gave a simple example: "Apple makes iPhones" and "Tim Cook is CEO of Apple" are just two disconnected statements on their own. A graph is what lets a system infer that Tim Cook is actually driving iPhone strategy, because it connects the two facts through what they share. That is closer to how human memory actually works, associating imperfectly, closing in on an answer rather than retrieving it whole. As Amy put it, describing her own experience trying to recall a film: "I'm probably saying, oh, it was about this topic, and it had this actor in it... you're making these associations over and over again until you get close, and then you can come up with the exact answer." She added, with a laugh, "I can never remember anybody's name anyhow," which is arguably the most human description of graph-based recall I've heard.
I mentioned a demo I return to often: searching a movie dataset for "blue aliens" when I can't quite recall the title, and landing on Avatar without ever typing the name. That's the same mechanism Amy was describing, getting close through association, then arriving at something exact.
Multimodal Amnesia: What Gets Lost When You Flatten Images, Audio, and Video
Amy strongly contends that true multimodality must encompass every data type, spanning audio, text, and structured data, rather than defaulting strictly to images and video. She described graphing the relationships within a single image directly: holding up a coffee cup and mapping it structurally, "it is to my right; it is in front of me, not behind me," rather than reducing the whole scene to one large embedding. Structure like that, she argued, exists in sound and video too, not just in pictures.
The most vivid part of the conversation was about what gets lost the moment multimodal data gets flattened into something more convenient to store. I described a real case: converting a customer support call to a text transcript, and losing the fact that the customer was being sarcastic, sarcasm that then gets read back later as genuine positive feedback. I call this pattern multimodal amnesia, and Amy immediately took to the term. "I love that term," she said. "They lose some of the structural information."
She pushed the idea further with her own example. Picture drawing a hub-and-spoke network on a whiteboard, she said, a structure where everything routes through one central point. The moment you flatten that into an unstructured description, you lose the fact that removing the central node would break the whole system, information that was obvious in the structure and invisible in the summary. The same is true of an image: where an object sits relative to another, the angle, the distance, all of it is context that a flat caption throws away.
"And sound, oh my goodness," she added, "sound is so full of contextual clues, like Doppler effects, that we don't even think about."
Vector similarity alone has its own version of this gap. Amy's example: "the room goes dark" could mean someone switched off a light, or pulled down the blinds. Linguistically, those two phrases sit far apart. Conceptually, they describe the same event. A pure embedding search built on linguistic similarity misses that connection entirely. A graph, tracing structural and conceptual relationships rather than word choice, is what catches it.
We've written before about what real multimodal support actually requires, not just a vector search that returns a URL, but access to data in the format users actually need. Read more in What Does Multimodality Truly Mean For AI?
What a Context Graph Actually Is: A Procedural Record, Not a Static Knowledge Base
We spent real time trying to pin down a term that has lately been used quite broadly and yet quite loosely across the industry: context graphs. Amy's distinction: a graph that simply stores facts is useful but passive. A graph that enables reasoning also carries ontologies, hierarchies, and rules, the kind of structure that lets a system understand that a grandfather cannot also be a father's son, not because it looked that fact up, but because the rule makes it so.
A context graph, in her framing, is something more specific. It's less a knowledge base you search, and more what she called "a procedural record," closer to a decision log than a static set of facts. She grounded the distinction concretely: a knowledge graph for Caterpillar equipment is what you search when you need to fix a specific machine, stable facts about how the equipment works. A context graph is the procedural record of what actually happened during a specific repair, an operation that emerges over time rather than a fact you look up. "It has much more of a right now feeling to me," she said, "what happened right now, why was this decision made right now." That's a meaningfully different object than a knowledge graph of stable facts about a domain, even though both get called graphs.
This is territory we've dug into separately: what was considered, what was rejected, and critically, whether a decision turned out to be right in hindsight, are all part of the reasoning environment a real context graph needs to capture, not just the decision itself. More in Context Graphs and Their Implementation: The Missing Layer Between Human Judgment and Machine Agency
The Layers of Machine Cognition: Knowledge Graphs, Multimodal Association, and Context Graphs
Asked how knowledge graphs, context graphs, and multimodal representation all fit together, Amy described the whole thing as a stack, or as she put it, a series of disks.
At the core sits the graph of facts. Above that, associative intelligence across modalities, connecting things the way humans naturally do. Above that, a layer where context graphs and operational intelligence come together into what she called a cognitive world state, or, borrowing a term from someone she'd spoken with, an "environmental graph": the actual environment an agent is reasoning inside, moment to moment.
Where Teams Get Graph Modeling Wrong: Under-Structuring, Over-Engineering, and Entity Resolution
I asked Amy where the real bottleneck sits today: infrastructure, or how people model the relationships in the first place. Her answer was immediate: modeling. The most common mistake she sees is treating a graph like a vector store, dumping data in without defining any schema or ontology, which produces something weaker than either a real graph or a real vector database. The opposite mistake is overengineering the schema too early, trying to get the perfect data model on the first attempt rather than starting flexible and letting it evolve. "It's very common for people to want to create the one perfect data model right out of the bat," she said. "But you don't know how it's going to operate in your environment."
We've written before about why this happens: most teams already have graph-shaped data and don't recognize it as such, which is often the real barrier, not a lack of graph technology. More in The Misunderstood World of Knowledge Graphs
One fix she called genuinely essential to the success of any of these efforts: entity resolution (something our Episode 1 guest had also emphasized as a systems problem to constantly resolve). Recognizing that John, Johnny, and John John Jr. might be the same person, or that Google, Google Inc., and Alphabet might need to resolve to one entity rather than three, is basic, unglamorous work, and skipping it is a common, avoidable failure.
Her closing observation tied the whole conversation together: the teams that do well generally aren't trying to build every piece of this themselves. They lean on infrastructure built for exactly this problem, and spend their own time on the part that's actually differentiated, the business logic and domain judgment only they have.
"That's where your competitive advantage is," she said. "You don't want to spend your time trying to overengineer or build four different types of databases or stores for the different specialized types." (thank you for that shoutout for ApertureDB!)
Amy has spent this conversation giving language to something I've been calling the neural backbone of an organization, the structural map underneath it. She's the architect who helps us see past the context window. For more from her, find her on LinkedIn or at GraphGeeks.
This is the second episode of The Cognitive Layer. Full conversation available on Spotify and YouTube.